TravelHardware
The travel tech I actually use
The power bank, chargers, adapters, two pairs of headphones, and folding stand I carry when I travel, with the tradeoffs that keep each one in my bag.
Notes from the workbench
The written side of what I build, break and figure out. Experiments, useful detours, and what I'd do differently.
Showing 1 to 10 of 51 posts
The power bank, chargers, adapters, two pairs of headphones, and folding stand I carry when I travel, with the tradeoffs that keep each one in my bag.
From an unopened base M6 Mac mini to a useful local AI chat, with the setup delays and one oversized model choice along the way.
One main assignment became three animated lessons, roughly 18 minutes each. My recorded experiment with Opus 5.5, Manim and synthetic narration.
A personal rant about model fatigue, useful improvements, shallow demos, and the local AI projects I want to finish.
Four CachyOS game captures on Strix Halo, the North America Linux adoption figures I reviewed, and why I may test Fedora next.
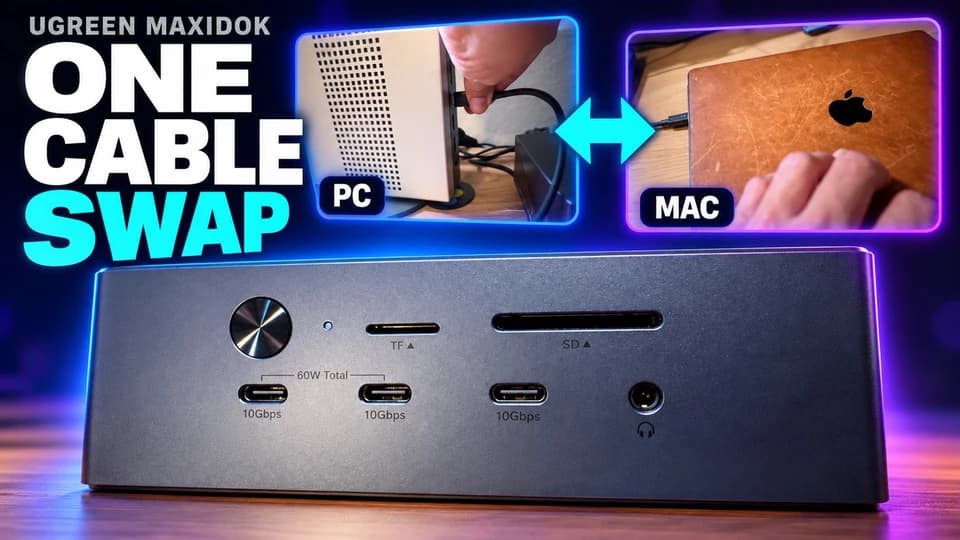
My UGREEN Maxidok setup with a GMKtec EVO-X2 and 2021 MacBook Pro: one host-cable swap, four SSD options for later, and the bandwidth limits I have not tested.
I tested Qwen 3.8 Flash-Next on Halogen across 72 coding runs: 66 passes, faster generation at longer context, and the limits of comparing two different configurations.
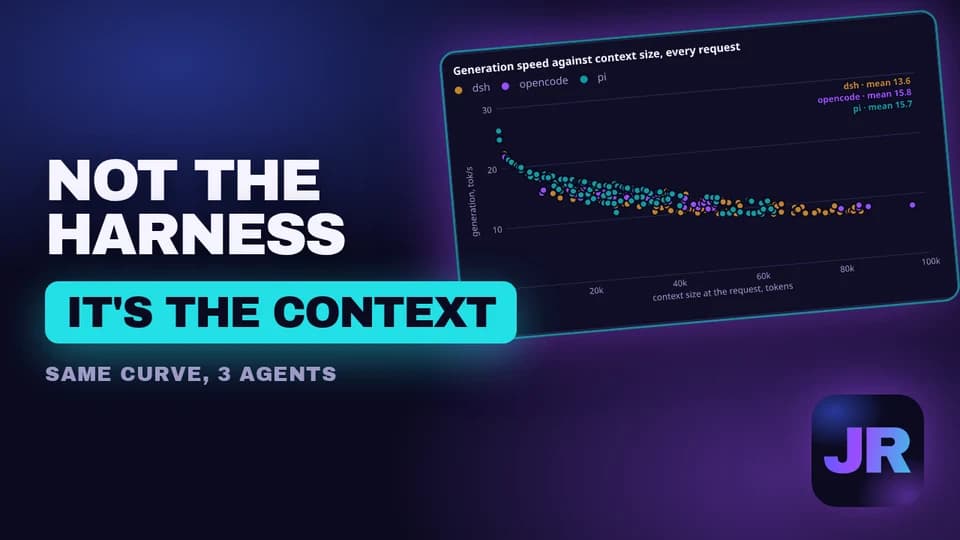
Qwen 3.8 Flash-Next felt fast in chat and slow in my overnight agent runs, so I ran six coding tasks on OpenCode, Pi and DeepSeek Harness at xhigh thinking on a 128 GB Strix Halo. 17 of 18 came back done. It is not the harness: generation falls from about 15 tokens a second under 25k context to about 8 past 75k on all three.
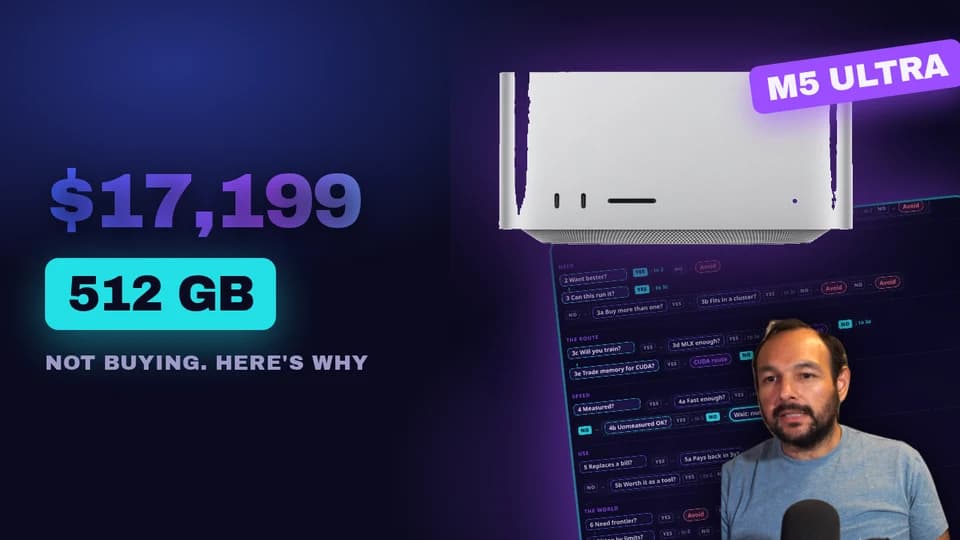
The M5 Ultra Mac Studio is a much better machine than the 128 GB box I run everything on, the 512 GB tier is tempting for the biggest local models, and it would be a dumb financial decision. So I built an interactive yes/no decision tree: pick the chip, memory, machines and the model you want, and it lands on buy at launch, wait, avoid, or a CUDA box instead. I walk my own answers through it. It says wait.
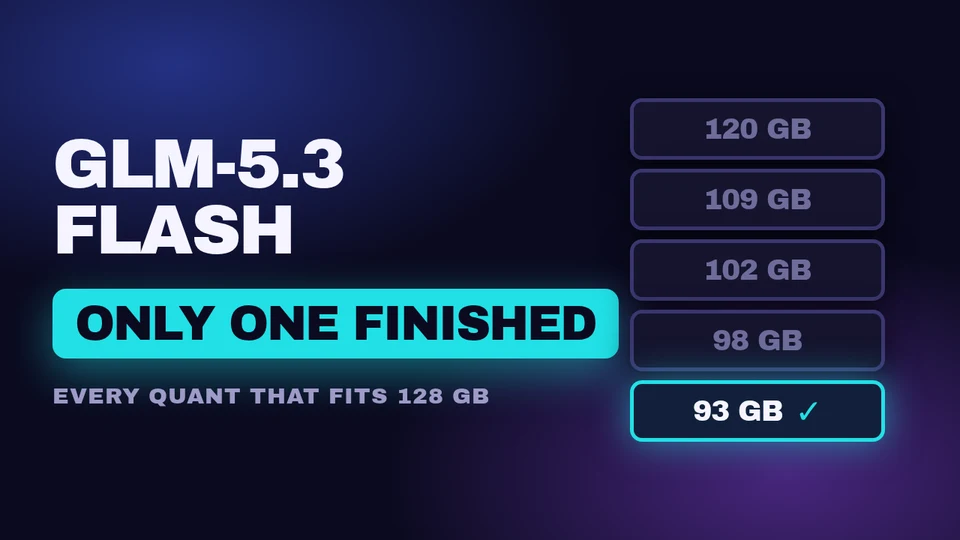
Every Unsloth quant of GLM-5.3-Flash that fits a 128 GB Strix Halo desktop, 93 to 120 GB, through the same four one-shot tests at reasoning low, high and max. Five files fit, speed is flat at 8 to 10 tokens a second, only the smallest file finishes the exam, high finishes one test in twenty, and max loops on one word for three hours. Every output and number on the results page.
Keep figuring it out with me
Get the written side of each video on Substack. What I tried, what worked, and what I learned along the way.